Sponsor: Do you build complex software systems? See how NServiceBus makes it easier to design, build, and manage software systems that use message queues to achieve loose coupling. Get started for free.
“We switched to event driven architecture. Now we can’t debug anything.”
A member of my channel shared a post with me where a team went all in on event driven architecture and ran into a bunch of problems.
The thing is, they’re not wrong about the pain they experienced. But the problems weren’t directly because of event driven architecture. They were mostly caused by how they understood it and how they were applying it.
So let’s break down the five pain points they had, why they had that pain, and how you can avoid it.
YouTube
Check out my YouTube channel, where I post all kinds of content on Software Architecture & Design, including this video showing everything in this post.
Where They Started
Before switching to event driven architecture, they had a REST based system. Really, that just means HTTP in this case, with services calling other services.
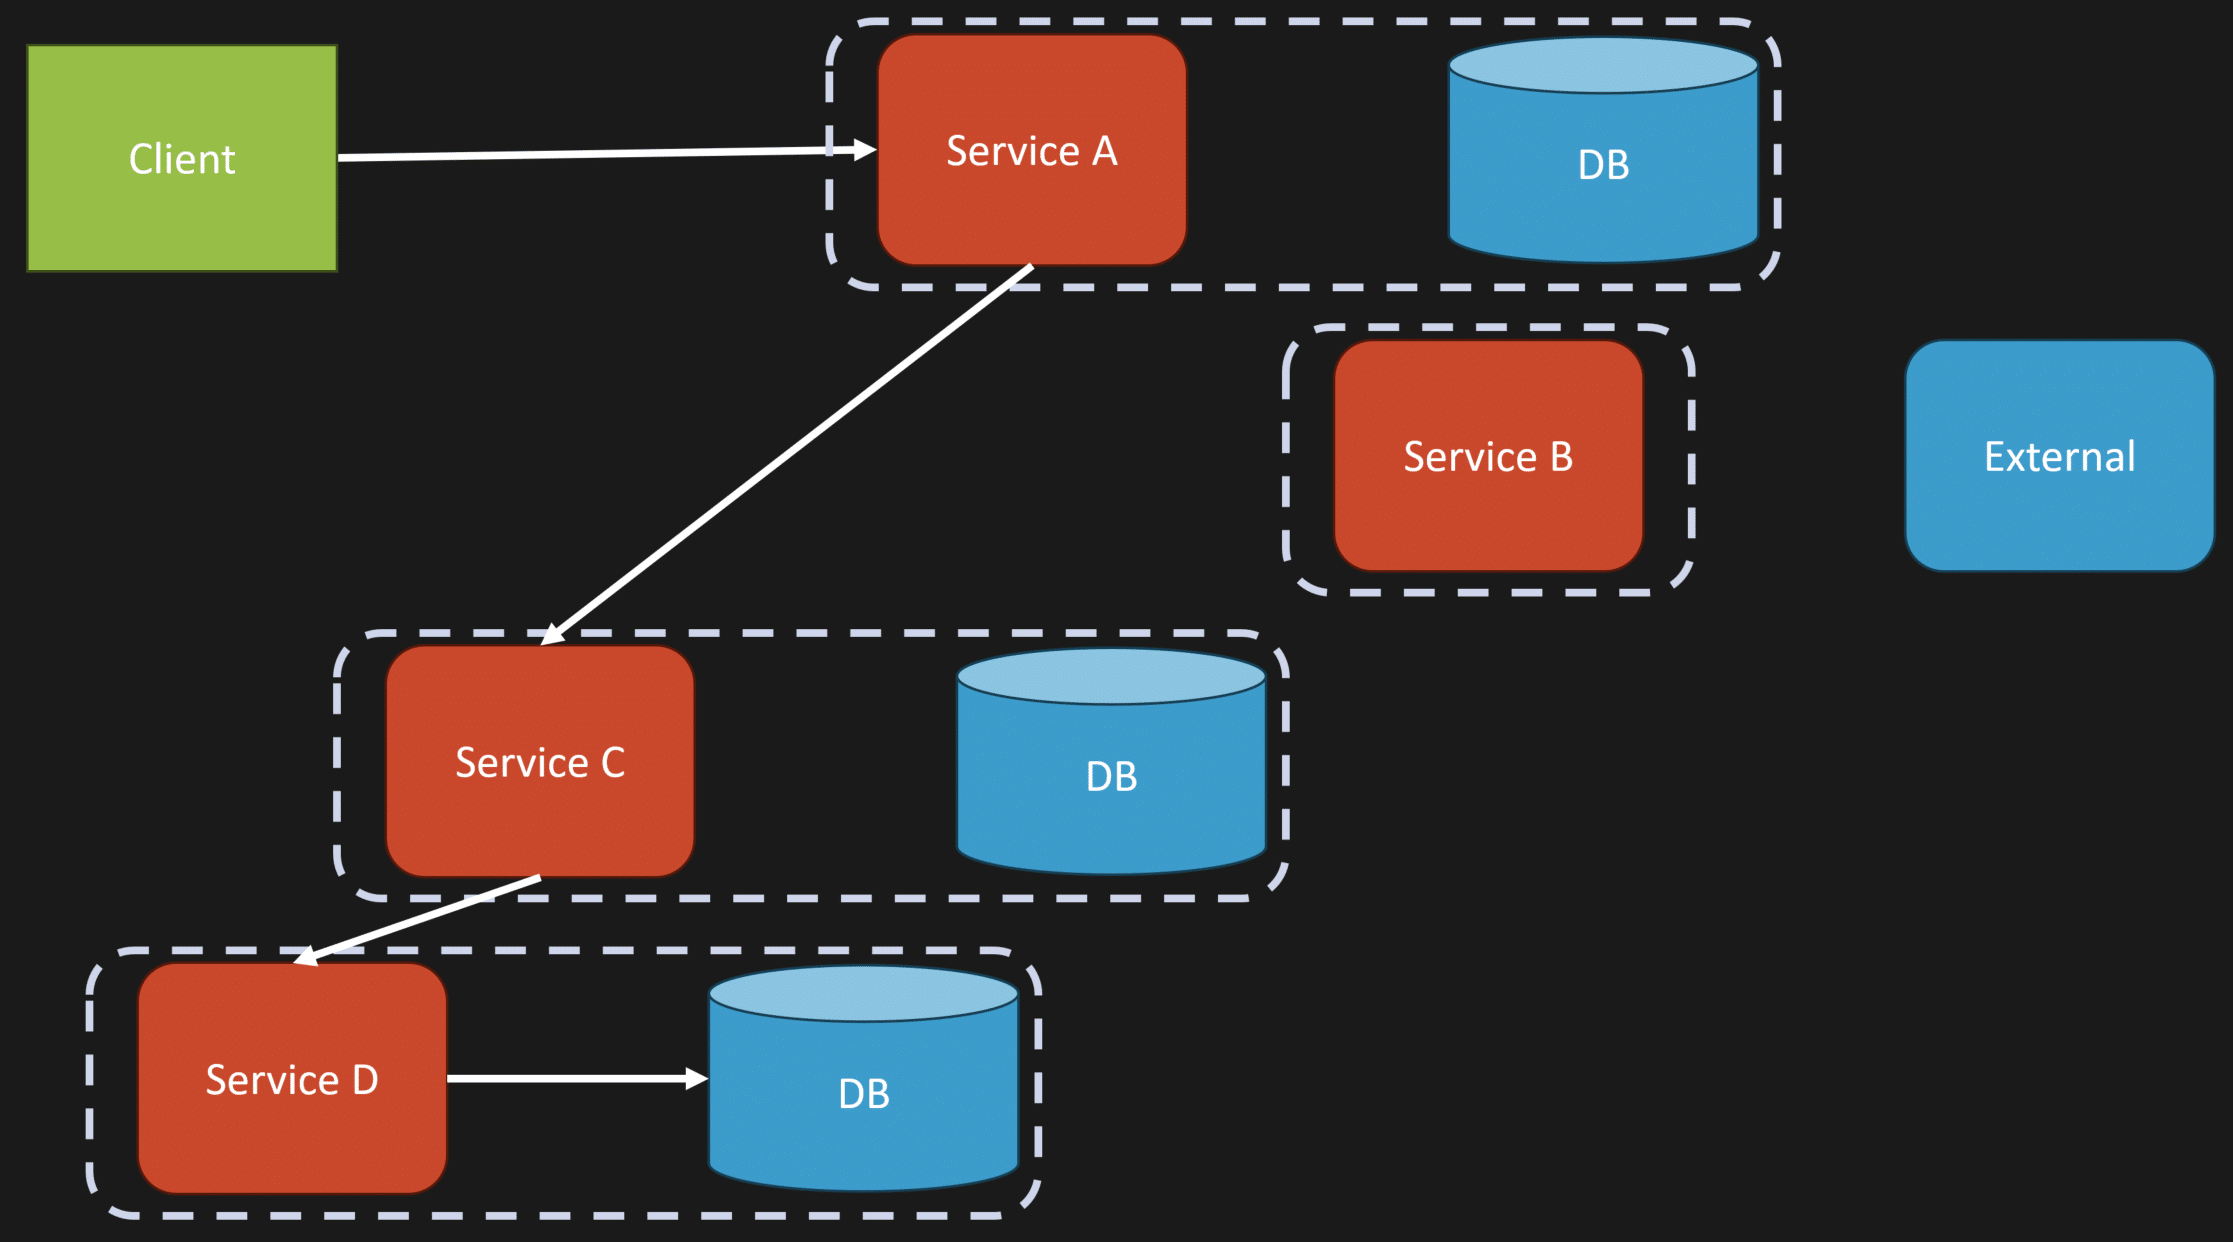
Imagine a client makes a request to Service A. Service A updates its database and then calls Service B. Service B might call something external. Service A also calls Service C, which has its own database. Maybe Service C calls Service D.
Eventually all of this works its way back until a response is returned to the client.
If that sounds like a disaster, well, it was.
They described it as a spaghetti mess of cascading HTTP calls, versioning nightmares between contracts across all these different services, and a very brittle orchestration layer.
So they moved toward asynchronous messaging and Kafka.
That solved some problems, but it introduced others. Or more accurately, it exposed some misunderstandings.
Problem 1: Tracing Ended at Kafka
Their first problem was tracing, specifically tracing asynchronous workflows.
With their existing HTTP based system, maybe the frontend called the ordering service, which called the payment service, which called the email service.
Using something like OpenTelemetry along with Zipkin, Jaeger, or another tracing tool, they could see that entire flow.
Then Kafka came into the picture.
Now the order service produces an event, and you have multiple services listening to different topics. Maybe the payment service handles something. The email service handles something else. The inventory service does something else.
For them, that completely broke their visibility into what was happening as part of the workflow.
This is absolutely a pain. You need good visibility and good tracing in any distributed application.
But OpenTelemetry works just as well in an asynchronous system as it does in a synchronous system using HTTP between services.
This should not be the problem.
What they likely had was a tooling problem.
They may have come from a more mature web framework where tracing was already integrated and simply worked out of the box. Then they moved to asynchronous messaging where their tooling didn’t provide the same experience.
Depending on what you’re using, that tracing should also work with asynchronous messaging.
I see this often when people use the SDK directly for whatever messaging system, event log, or message broker they’re using instead of leveraging a messaging library that already has this functionality built in.
To me, this is largely a tooling issue. Tracing asynchronous messaging is a solved problem. You just need tooling that actually supports it.
Problem 2: Dead Letter Queues Became Garbage Dumps
Their second problem was dead letter queues.
They sound helpful. You have somewhere to isolate messages that failed.
But in their case, they became a graveyard of mystery failures.
Dead letter queues are great, but they’re just storage.
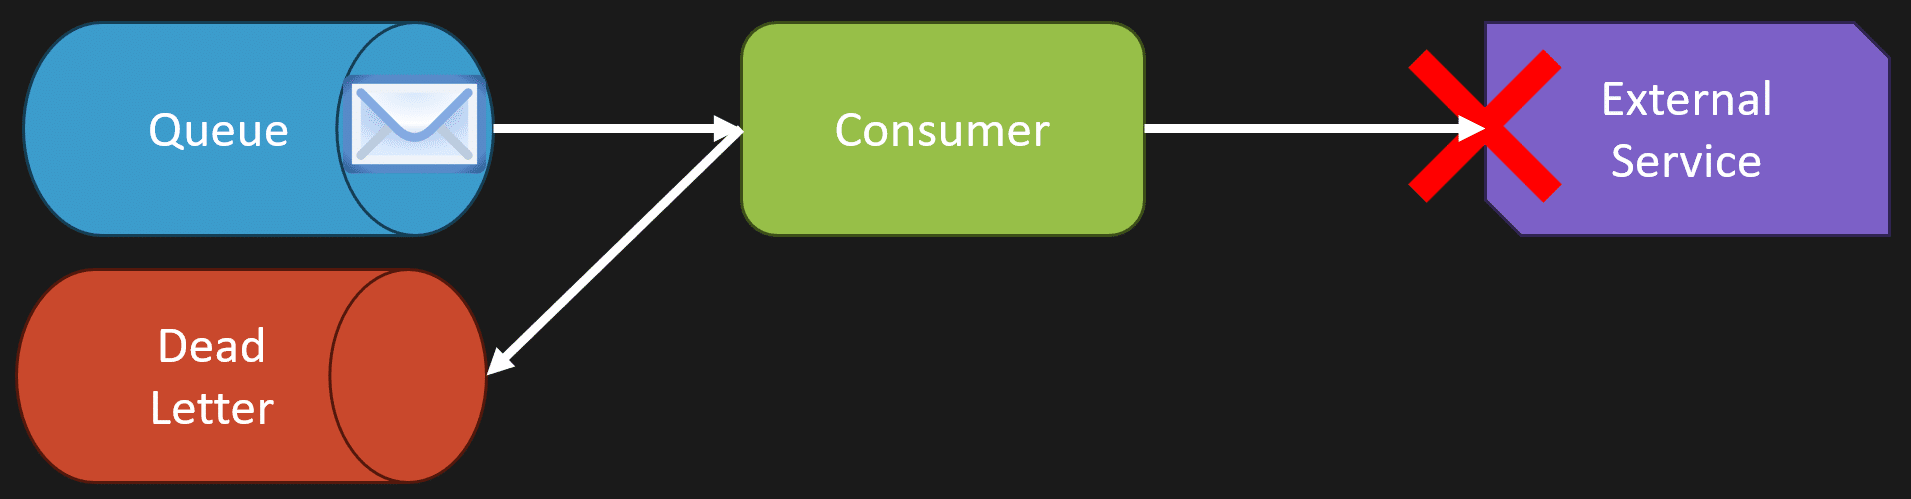
Imagine you have a queue with a consumer processing messages. As part of processing a message, that consumer needs to call an external service.
The external service is failing.
Maybe you have a retry with some type of backoff. It tries again. It still fails.
Eventually you move that message to a dead letter queue.
That dead letter queue is simply somewhere to put the message so you can deal with it later. Maybe somebody manually retries it after the underlying problem has been resolved.
But a dead letter queue without any way to inspect the message, replay the message, or see the errors and exceptions that occurred while processing it is basically a black hole.
It isn’t useful by itself.
You need visibility into why the message failed. You need to correlate that message with the error or exception that actually occurred.
Do you need to fix something in your code?
Is it a poison message that will never succeed?
Was there simply a transient failure while calling an external service, and if you process the message again now that the service is available, everything will work?
You need visibility into both the failure and the message itself.
Again, this comes back to tooling and observability.
Problem 3: Fire and Forget Equals Debug and Regret
I have to admit, I like that title.
Their comparison was that REST is like ordering at a restaurant. You place an order and wait for confirmation.
You sure about that?
I actually use restaurants all the time to explain asynchronous workflows.
You arrive at a restaurant and whoever greets you brings you to a table. They don’t stand beside your table waiting for you to decide what you want to order.
They go perform some other action. Maybe they greet another customer and bring them to another table.
The entire workflow is full of asynchrony.
Eventually the wait staff takes your order and enters it into the point of sale system. That communicates to the kitchen that there’s an order that needs to be prepared.
The kitchen picks that up asynchronously and starts cooking your meal.
When the order is ready, there’s effectively another message saying that the food is ready to be picked up. Somebody gets it and brings it back to you.
It’s full of asynchronous workflows. You just need to embrace that.
But the biggest red flag in their example, and something I see over and over again, was that they were forcing everything to be an event and everything to be asynchronous.
It doesn’t need to be.
Not Everything Is an Event
They described events as throwing a note into a room and hoping somebody reads it.
Not really.
What they’re describing is publish-subscribe, and that’s the point.
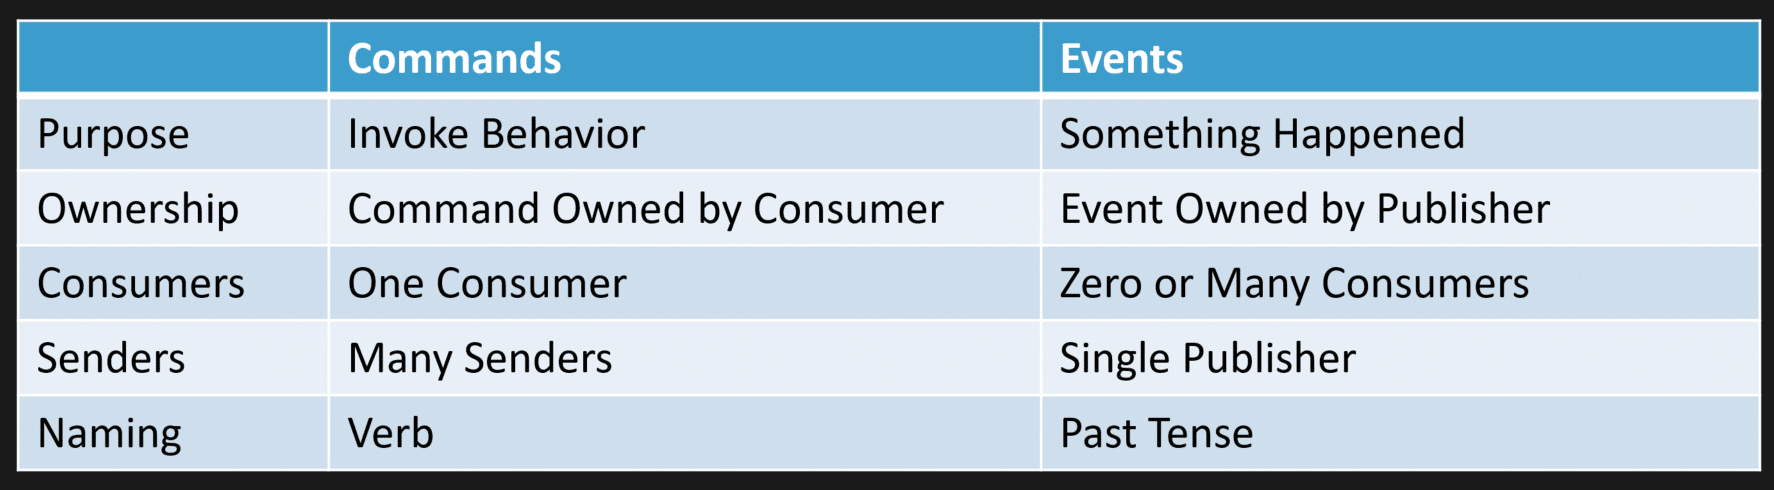
Events are facts. Something happened.
If you publish an event, you as the producer don’t care if there are any consumers.
There might be no consumers. There could be a thousand consumers.
As the publisher, it doesn’t really matter.
You own the schema because you’re producing the event. The event represents something that occurred inside your boundary.
That’s very different from a command.
Commands are about invoking behavior.
A command is owned by the consumer because there should be one boundary responsible for handling that command. There could be many different senders depending on how you define your boundaries, but there is one logical consumer.
Commands are generally named using verbs because they represent actions you want to invoke.
Events are different.
Events are facts. Something happened and you’re notifying some other part of your system.
Events are owned by whoever publishes them because the event occurred within that particular boundary. There is one publisher, but there can be zero to many consumers.
Events are generally named in the past tense because they represent things that already occurred.
Commands and events have different utility. They’re different concepts.
Not everything needs to be asynchronous, just like not everything needs to be an event.
Some things naturally need to be synchronous.
Queries are an obvious example.
In their original HTTP based system, they were synchronously calling different services to perform different actions. That doesn’t mean you replace every one of those calls with an event.
You have to understand what can be fire and forget and what requires an immediate response.
There’s also the option of an asynchronous request and reply when you actually need it.
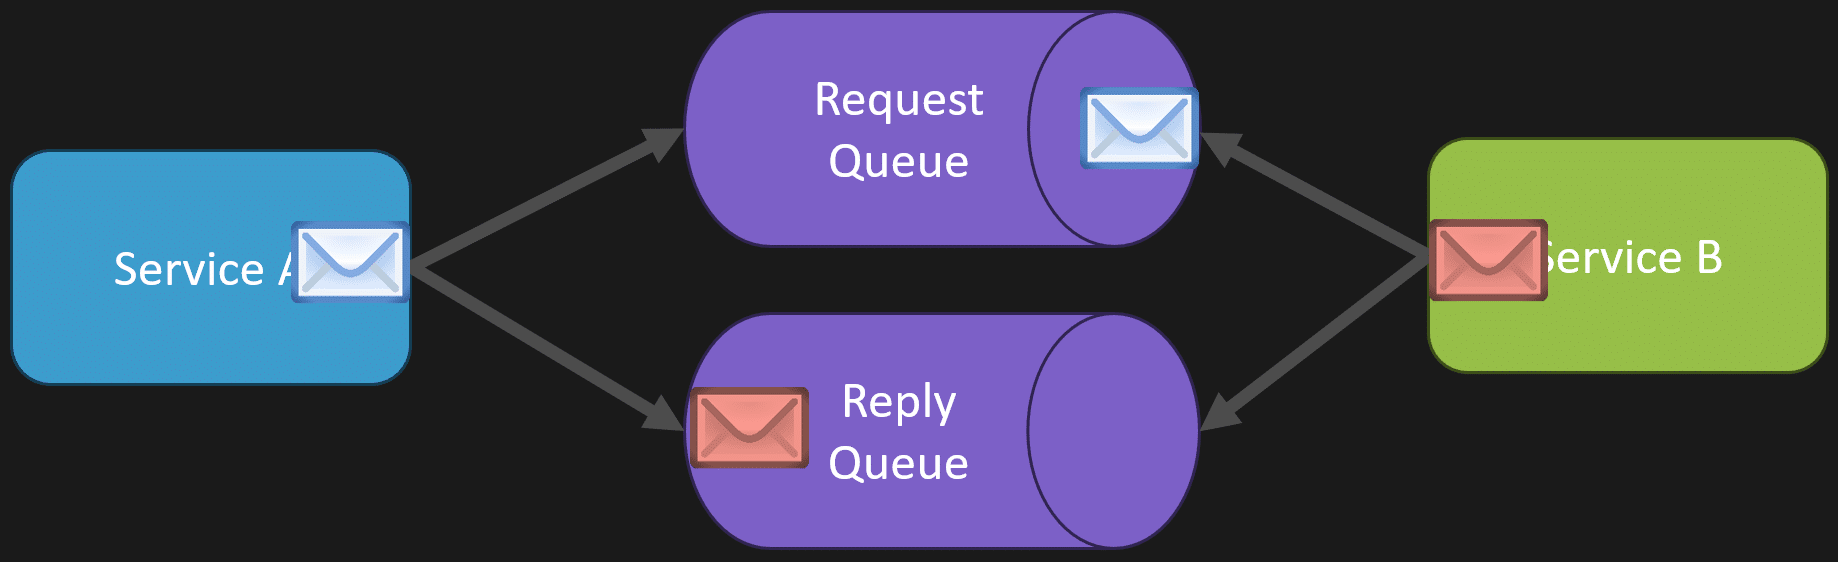
Maybe Service A sends a request that Service B processes asynchronously. Once Service B completes the work, it sends a reply message to a separate queue.
Service A consumes that reply and correlates it back to the original request.
Now it understands the outcome of that asynchronous processing.
That pattern can be completely reasonable. The problem is using it everywhere when you don’t actually need it.
Problem 4: Eventual Consistency Is Like Eventual Accountability
Another great title.
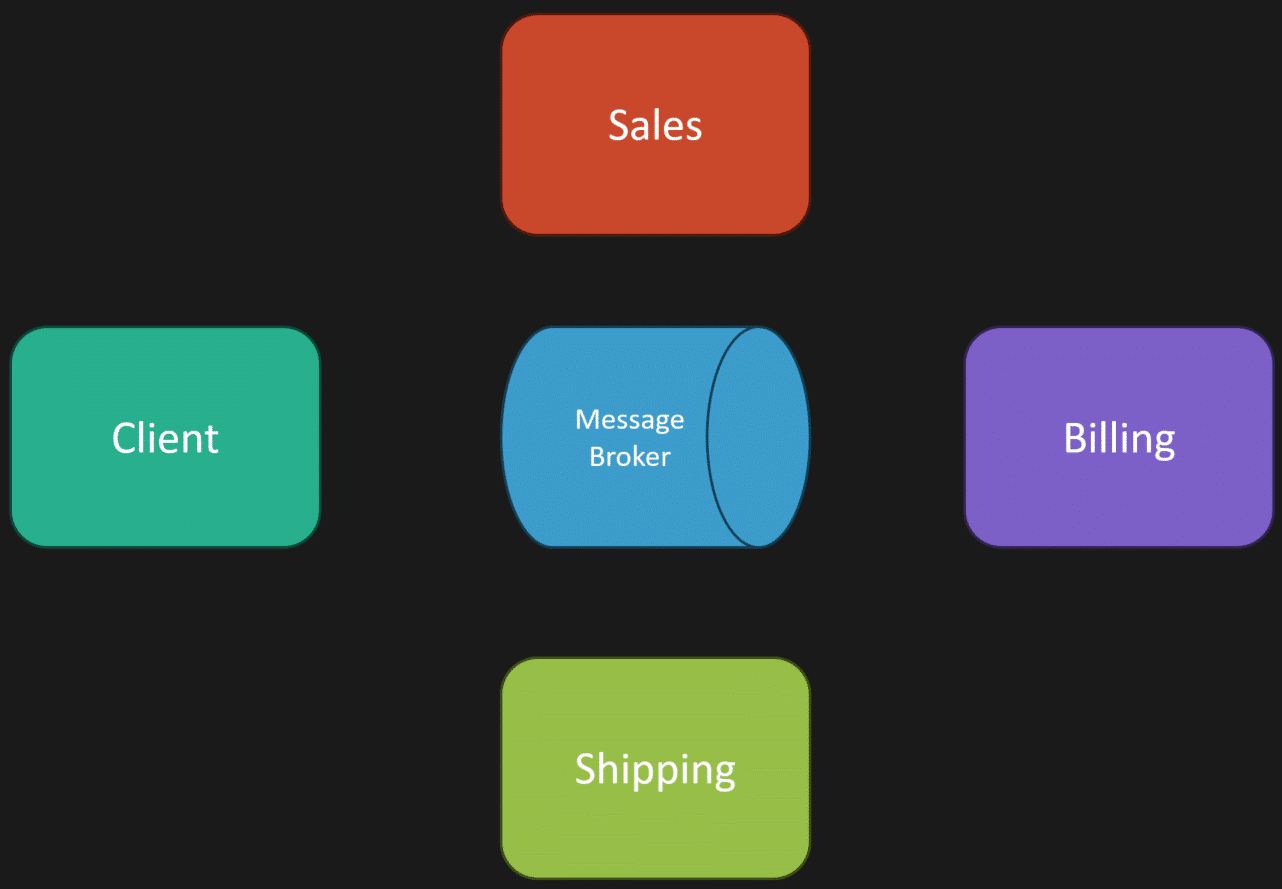
Imagine an order flows through four different services.
An order is placed. Inventory gets reserved. Payment gets charged. A confirmation email gets sent.
Then something fails.
Now you need to compensate.
Maybe you need to restock the inventory. Maybe you need to refund the payment. Maybe you need to cancel some other action that already occurred.
Absolutely. This is a problem.
Coordinating what happens when one part of a longer workflow fails can get complicated.
How do you know what completed?
What failed?
What compensating action needs to happen next?
This is exactly what the saga pattern is intended to address in an asynchronous workflow.
But here’s the thing: this isn’t necessarily easier in a synchronous system.
Think about having one long procedural workflow filled with service calls and try catch blocks.
Call one service. That succeeds.
Call another service. That succeeds.
Call the third service. It fails.
Now start figuring out which previous operations need to be undone. Add some nested error handling and compensating logic around all of it.
That can become a mess too.
The advantage of an asynchronous workflow is that you can have state associated with the saga. You can understand what has completed, what hasn’t completed, and where something failed.
Combined with dead letter queues and proper observability, you can see what’s actually happening.
Again, we come back to visibility and tooling.
Problem 5: Testing Became a Nightmare
Their final problem was testing.
Unit tests were fine, but integration tests became painful.
Now they were spinning up Kafka, mocking consumers and producers, and waiting for asynchronous side effects.
The problem here is trying to test everything across boundaries.
Remember, events are contracts. They’re not conversations.
They don’t go two ways.
This goes back to the distinction between events and commands.
Are you trying to invoke something?
Or are you telling some other part of your system that something happened?
From the producer’s point of view, what are you actually responsible for testing?
Are you publishing the event you’re supposed to publish?
That’s your responsibility.
From the consumer’s point of view, are you consuming that message and processing it correctly?
That’s what you need to test.
You don’t necessarily need one massive integration test that spins up your entire distributed system and verifies every side effect across every boundary.
Understand the contracts between those boundaries and test the responsibilities on each side.
Event Driven Architecture Isn’t Your Architecture
This is the part that gets missed.
Event driven architecture isn’t your architecture.
It’s just part of it.
It isn’t a full system replacement where you take every HTTP call you currently have and replace it with an asynchronous event.
That’s not the point.
A system can have synchronous communication, asynchronous communication, commands, events, queries, request reply messaging, and other patterns all working together.
It’s about the outcomes you’re trying to accomplish.
Not following a pattern everywhere because you decided your system is now “event driven.”
Join CodeOpinon!
Developer-level members of my Patreon or YouTube channel get access to a private Discord server to chat with other developers about Software Architecture and Design and access to source code for any working demo application I post on my blog or YouTube. Check out my Patreon or YouTube Membership for more info.